We are pleased to announce the release of zml/llmd 2026.11.3. This week brings an embeddings API, support for
decision models, and MXFP4/NVFP4 on Intel oneAPI. You’ll also find general bug fixes and improvements throughout.
A new versioning scheme
The version number looks a little different this week. Releases now use YYYY.MM.<revision>,
with a revision number for each release within the month.
Embeddings API
zml/llmd now implements the embeddings endpoints through POST /v1/embeddings and POST /embeddings with initial
support for the Qwen3-Embedding series.
You can pass a single string or a list of strings and request a smaller output vector with dimensions
when the model supports it.
curl http://localhost:8000/v1/embeddings \
    -H 'Content-Type: application/json' \
    -d '{"model":"Qwen/Qwen3-Embedding-0.6B","input":["First document", "Second document"], "dimensions": 32}'
Decision Models
This week, zml/llmd adds decision models via the /v1/systemone endpoint.
Decision models are designed to answer multiple-choice questions
and do it a lot faster than general-purpose LLMs. They are trained to reason about the choices and provide a single answer.
We have also implement a StartLux extension in which questions in a request can depend on one another, even when a dependency appears later in the list. The server schedules questions when their dependencies are complete and rejects cycles.
Here is a sample request/response:
curl -sS http://127.0.0.1:8000/v1/systemone \
    -H 'Content-Type: application/json' \
    -d '{
        "model": "startlux-models/StartLux-Decision-v1.1-0.8B-Instant",
        "state": "The animal sits on the mat, purrs and chases a red laser dot.",
        "questions": {
            "animal": {"type": "choice", "instructions": "Which animal is it?", "criteria": {"cat": null, "dog": "barks"}}
        }
    }'
{
  "answers": {
    "animal": {
      "type": "choice",
      "choice": "cat",
      "confidence": 0.9999995231628418,
      "probabilities": {
        "cat": 0.9999997615814209,
        "dog": 2.0826452384881122E-7
      }
    }
  },
  "usage": {
    "input_tokens": 54,
    "output_tokens": 0
  },
  "model": "startlux-models/StartLux-Decision-v1.1-0.8B-Instant"
}
Here’s a little demo of Google’s Diffusion Gemma playing Pac-Man via zml/llmd:
StartLux Decision Models
As a first release, we added support for the StartLux Decision models:
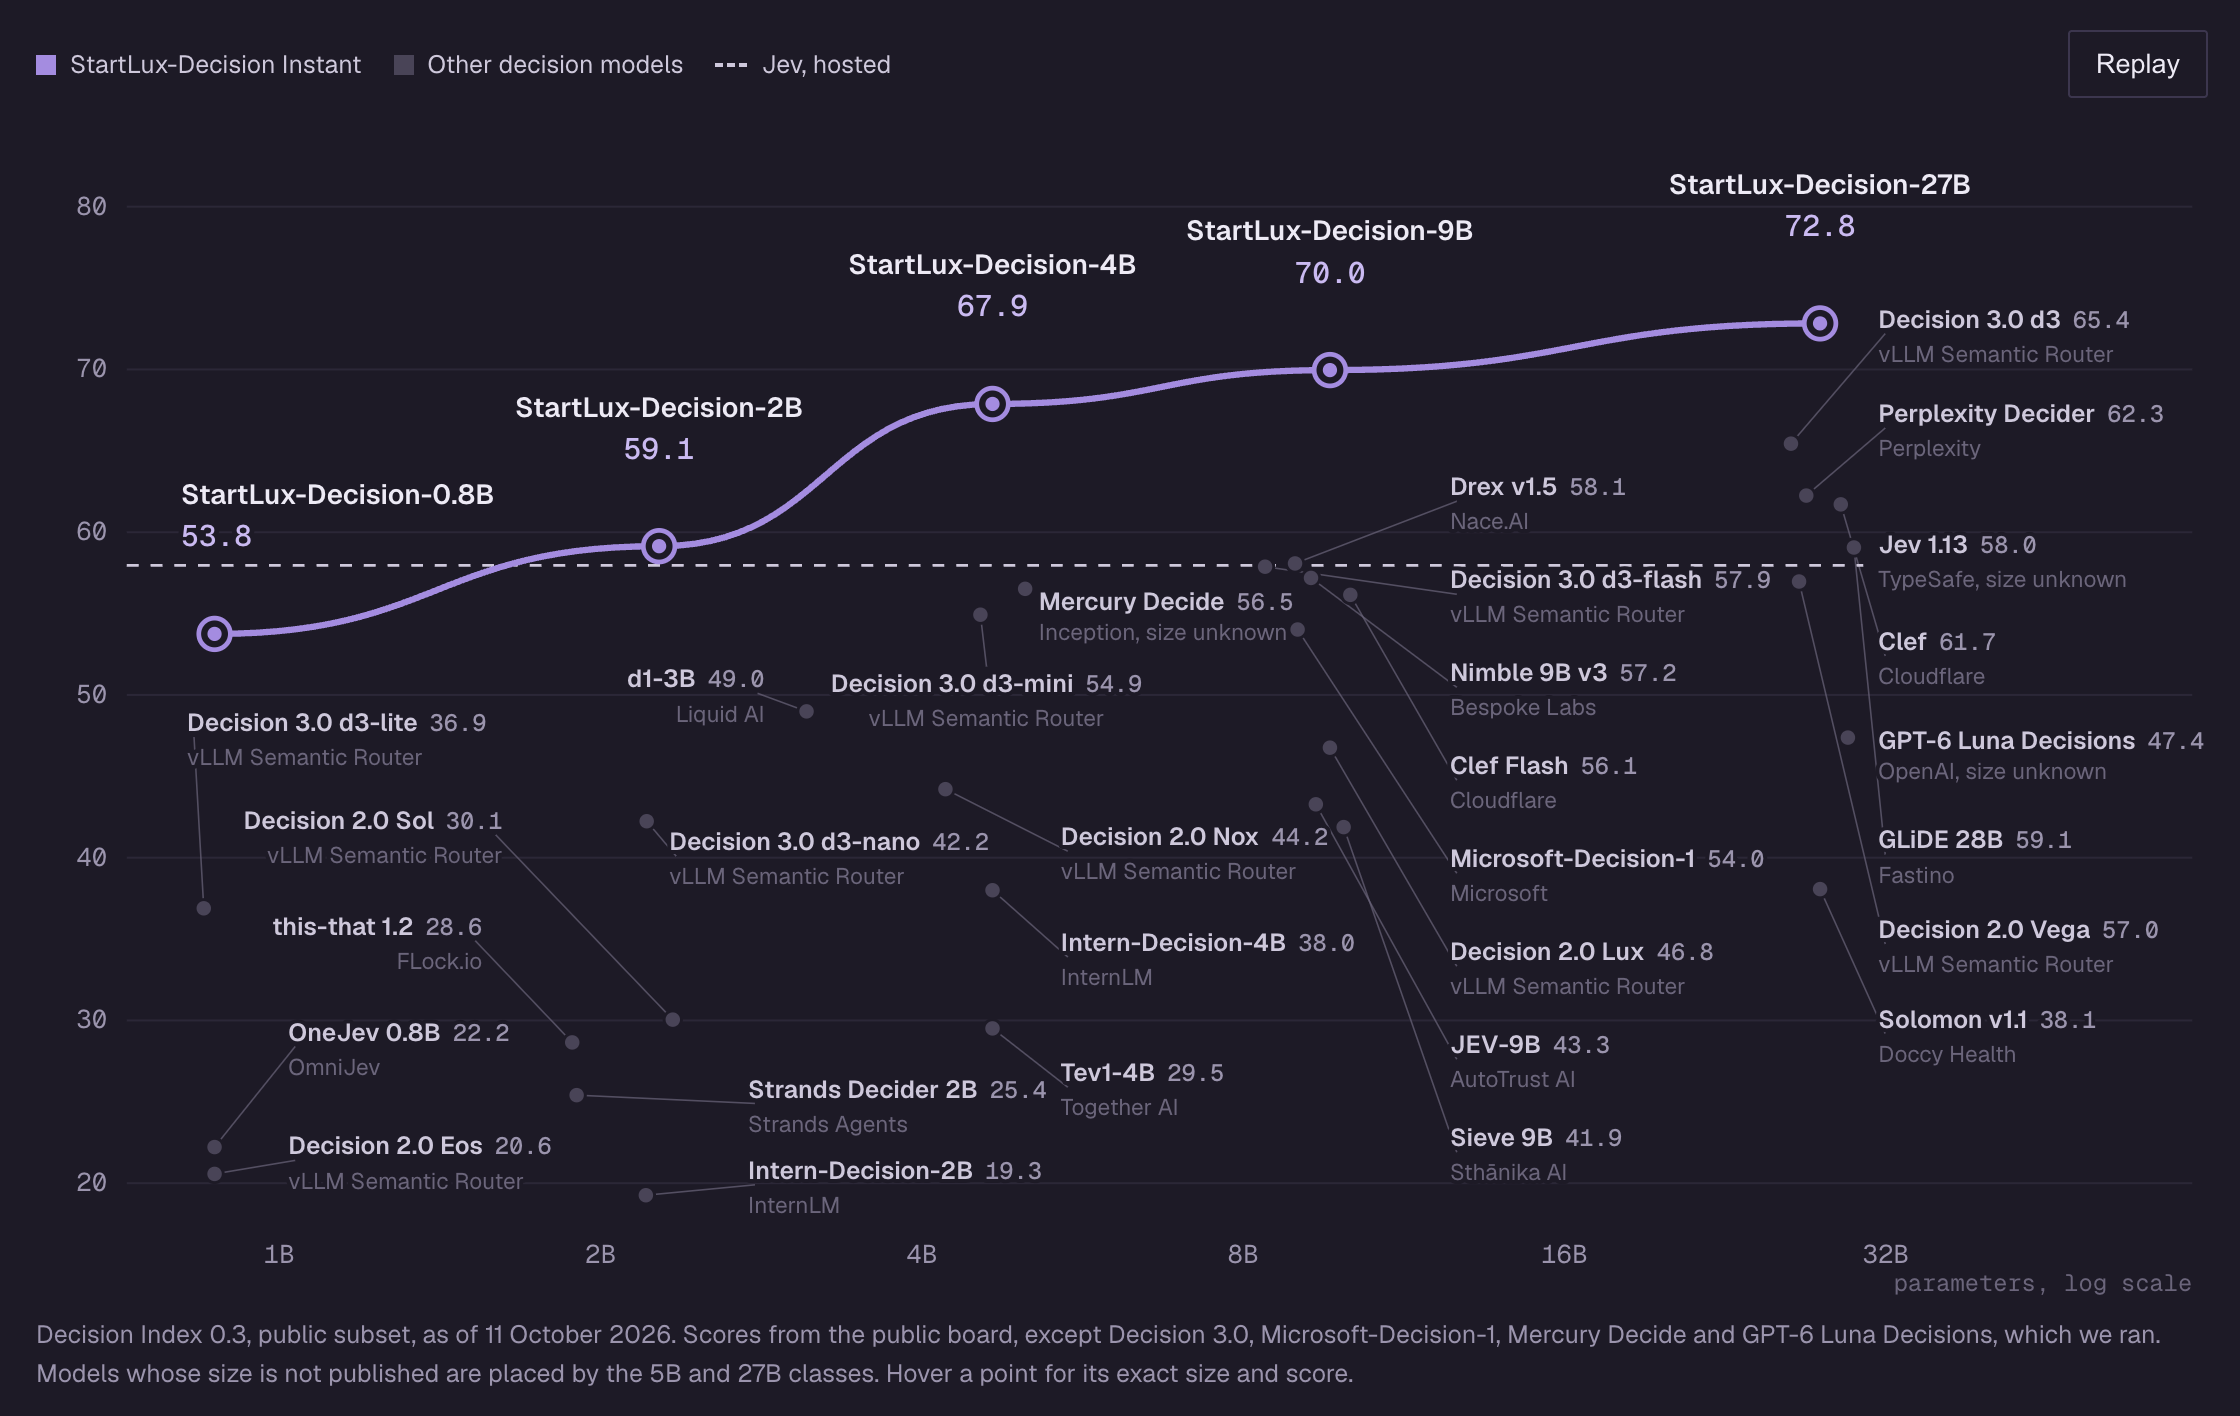
StartLux Decision models come in two variants. Instant answers in one pass. Autothink can spend more time
reasoning and try again when the first decision is uncertain.
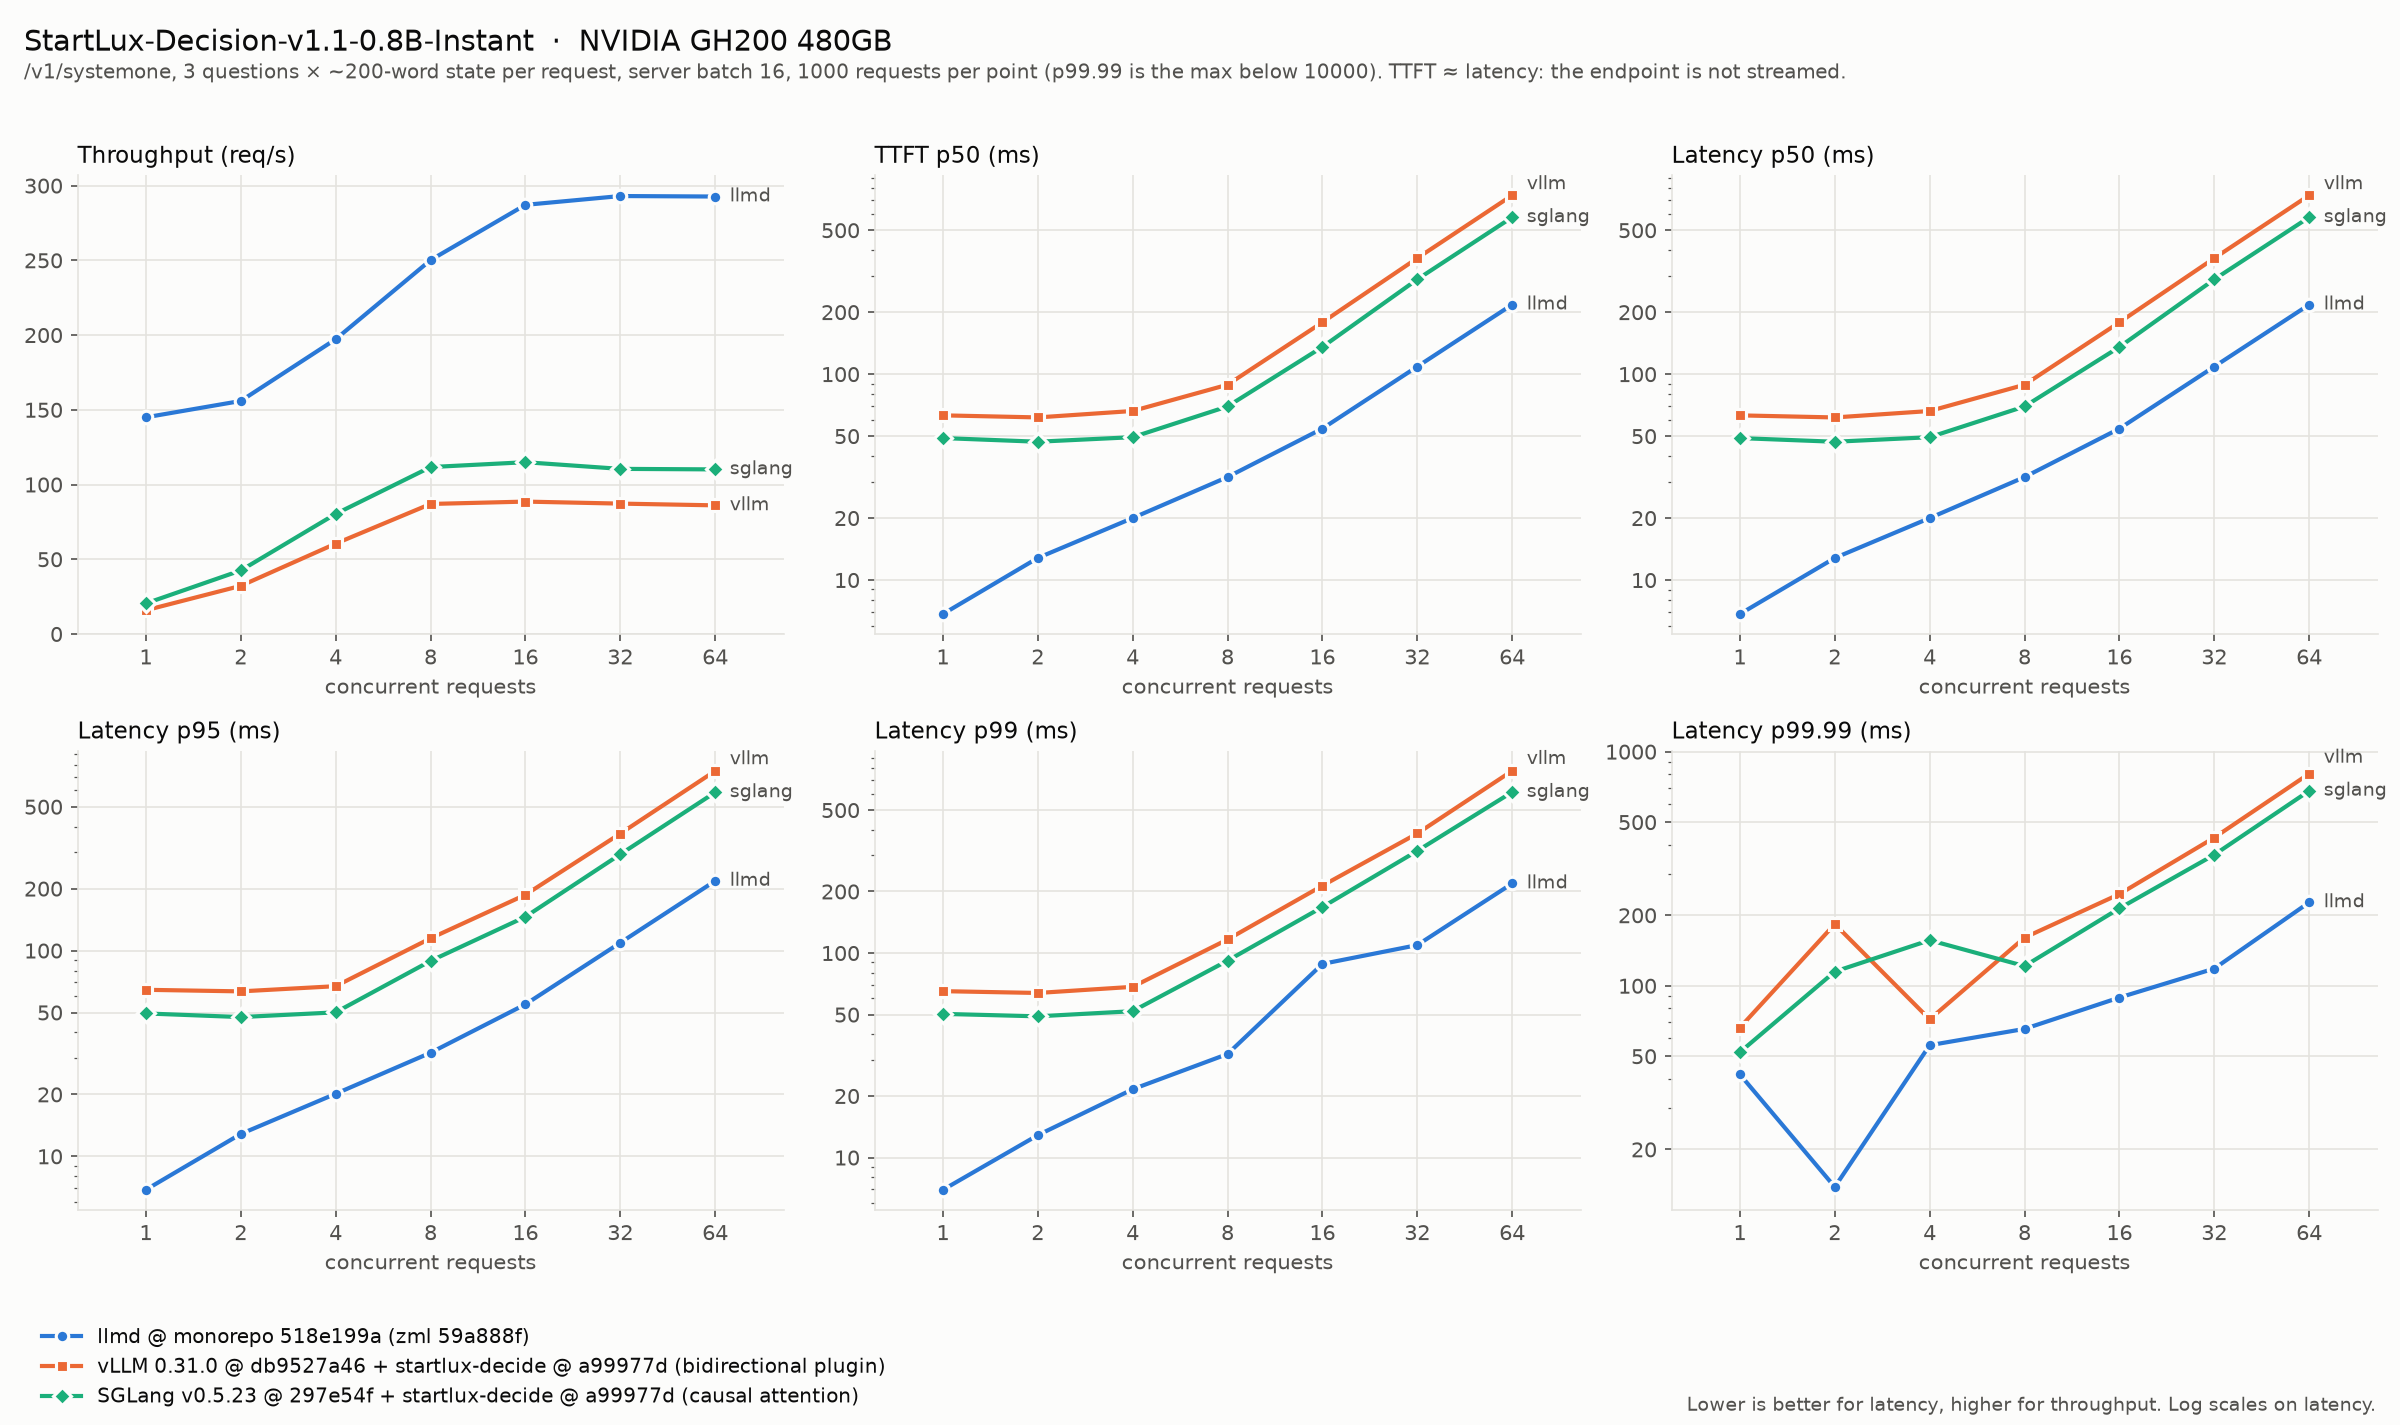
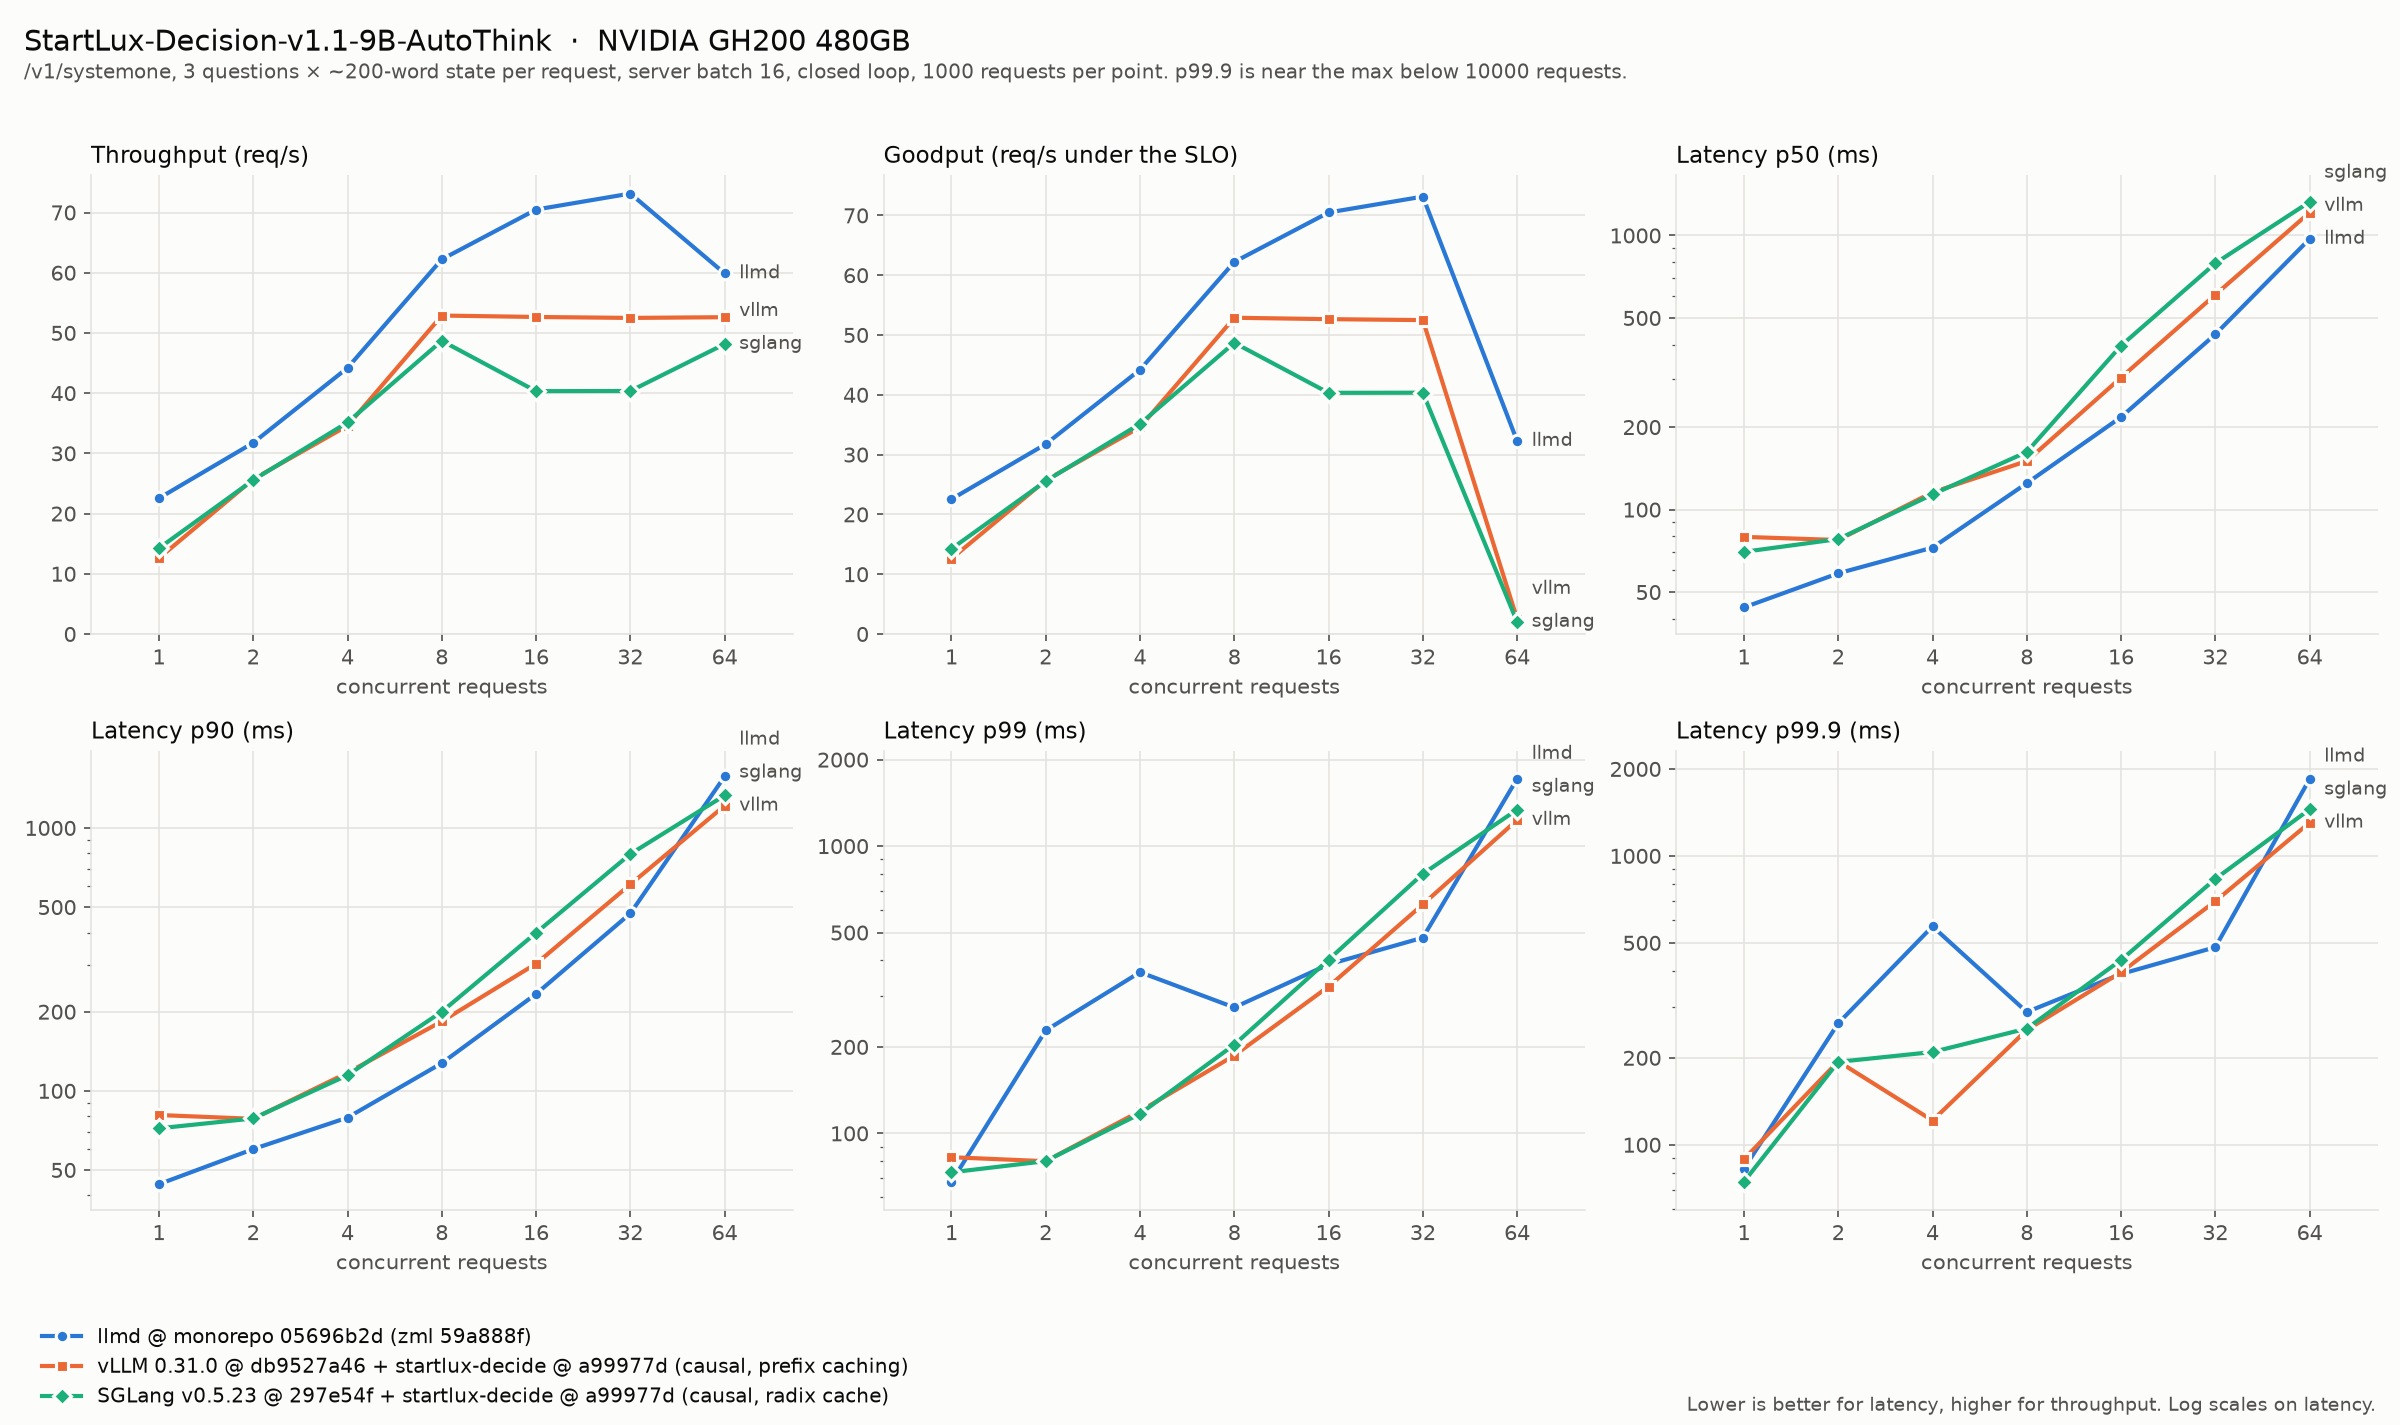
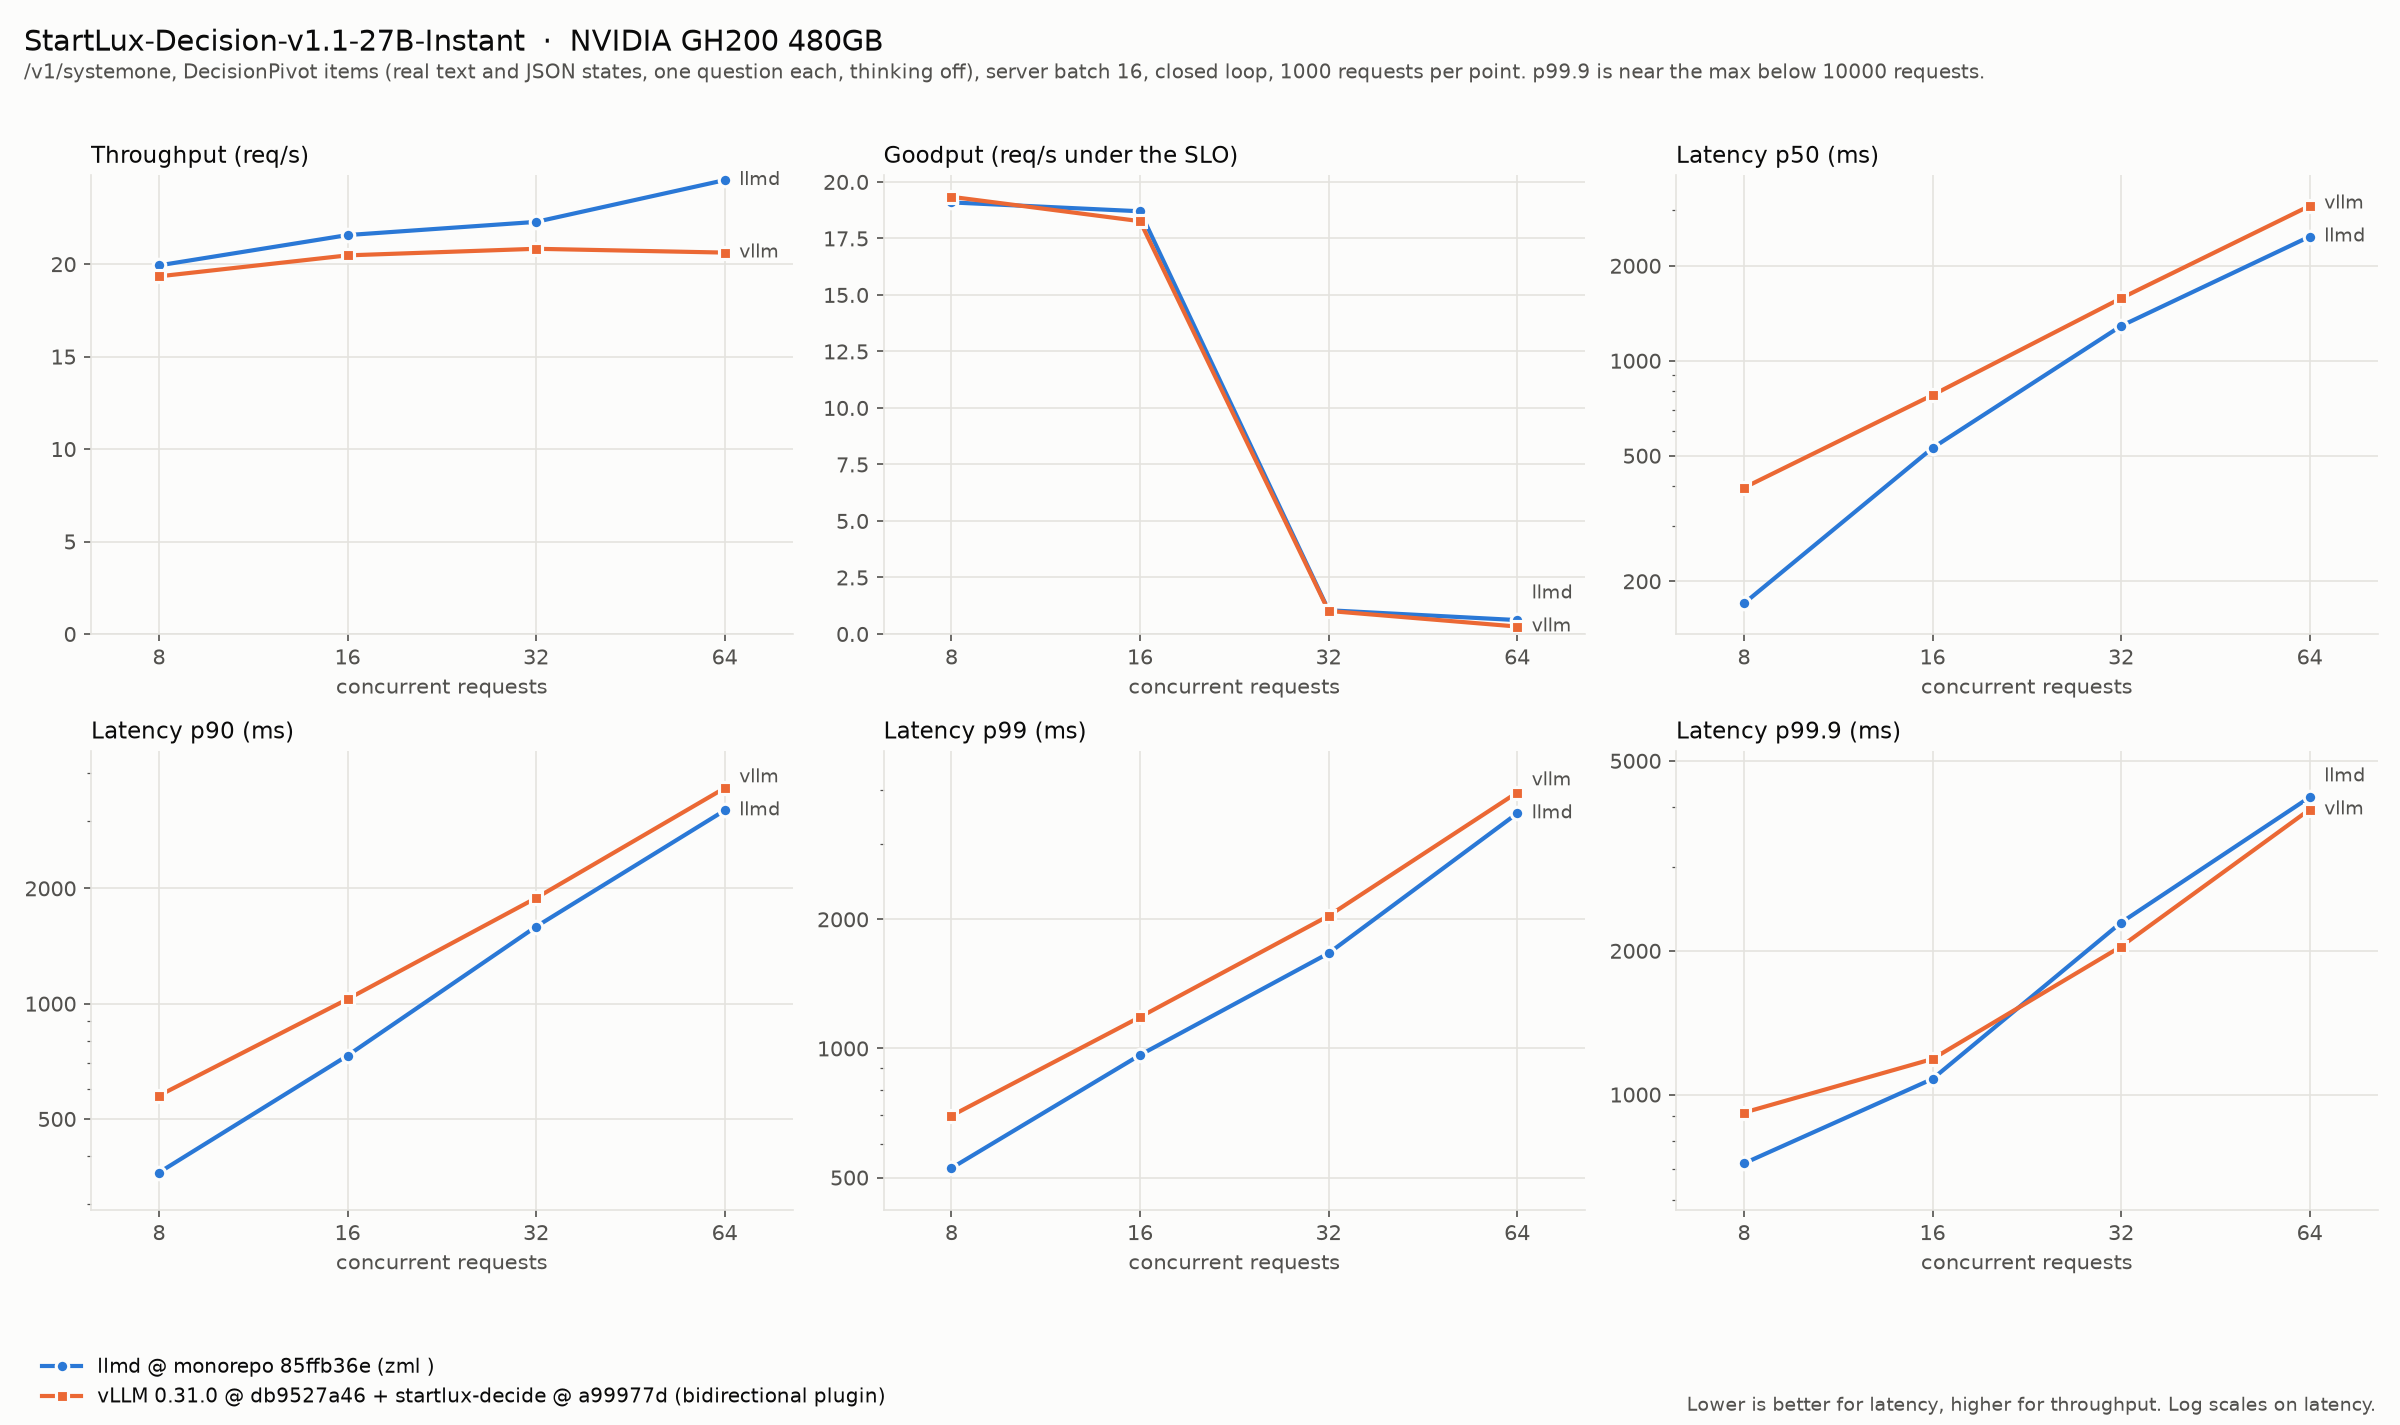
Here are the performance measurements vs vLLM and SGLang:
Regular LLMs in decision mode
You can send decision requests to a general-purpose LLM you’re already serving through zml/llmd. The same
checkpoint can handle chat requests and answer multiple-choice questions through /v1/systemone. Decision mode requests
are batched with regular completion requests inside the same forward pass, so you can use the same model for both workloads
if you choose to do so.
This release supports decision mode for Llama, Qwen3.5/3.6/3.8, Qwen 3.8 Flash Next, Gemma 4, LFM 3, and GLM 5.2. DeepSeek-V4.1 support is deferred pending a chat template fix.
DeepSeek-V4.1 Data Parallelism
DeepSeek-V4.1 gains support for --data-parallel. As with Llama, this lets you distribute requests and their
KV caches across groups of devices.
Intel oneAPI MXFP4/NVFP4 support
The Intel oneAPI backend can now run compatible MXFP4 and NVFP4 checkpoints. This lets you run models that were quantized for NVIDIA’s NVFP4 format transparently, with a nice performance boost and more memory savings.
Try it today
NVIDIA
docker run -p 8000:8000 --shm-size=256GB --gpus=all -e HF_TOKEN -it zmlai/llmd:cuda \
    --model=hf://Qwen/Qwen3-Embedding-0.6B
AMD
docker run -p 8000:8000 --shm-size=256GB --device=/dev/kfd --device=/dev/dri -e HF_TOKEN -it zmlai/llmd:rocm \
    --model=hf://Qwen/Qwen3.8-Flash-Next
Intel
docker run -p 8000:8000 --device=/dev/dri -e HF_TOKEN -it zmlai/llmd:oneapi \
    --model=hf://Qwen/Qwen3.8-27B
Google TPU
docker run --net=host --privileged -e HF_TOKEN -it zmlai/llmd:tpu \
    --model=hf://Qwen/Qwen3.8-27B
Apple Metal
brew install zml/zml/llmd
llmd --model=hf://Qwen/Qwen3-Embedding-0.6B